Engineering
Sandbox the Code, Not the Database
An AI agent needs its own database to test against. You can shrink the database to fit the agent, or leave the database alone and shrink the agent instead. Only one of those still answers questions about the table that does not fit.
 Stephen Nolan | Co-Founder and COO, DBGorilla·
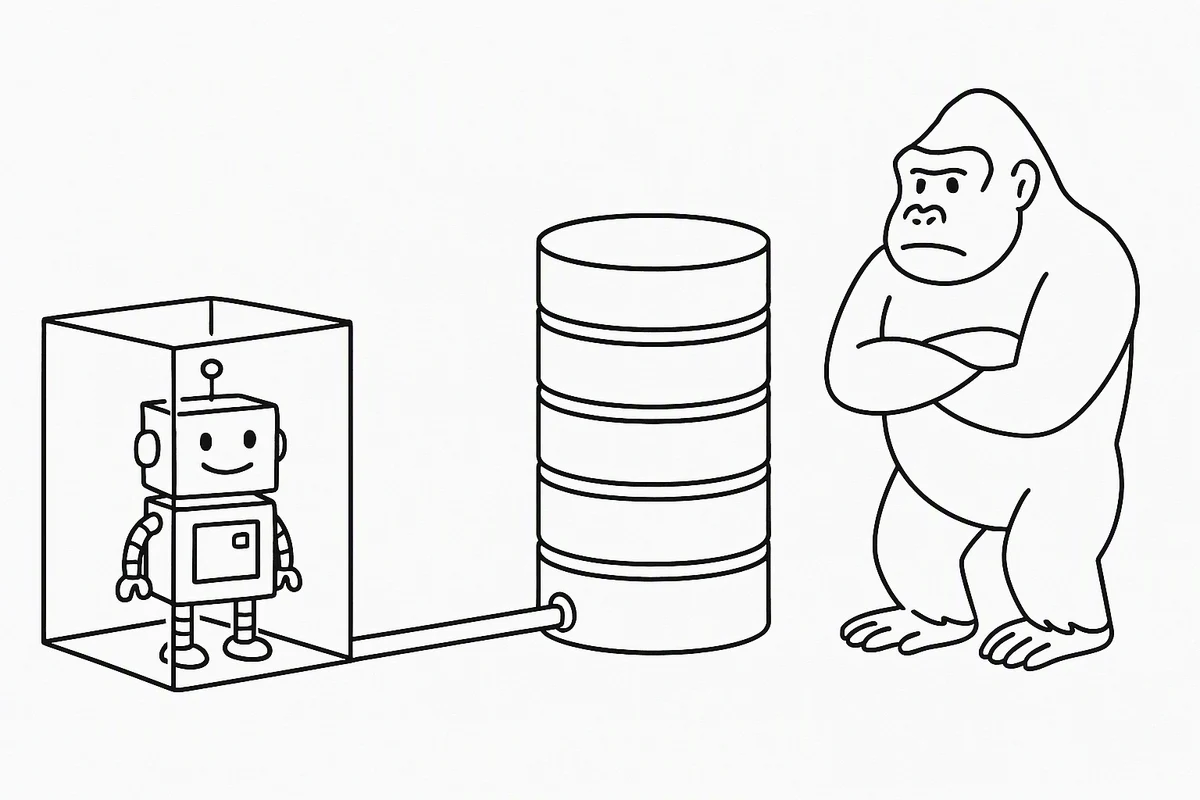
DBGorilla puts the sandbox around the agent’s code and gives it a separate Postgres database for experiments. That database carries production statistics and matches the production major version. We want the agent to test a change without changing the conditions that influence the query planner’s decision.
An engineer considering an index needs somewhere safe to try it. An agent needs the same thing, without access to change production. We first tried putting the database inside the agent’s sandbox with PGlite, then moved the database outside it when we needed concurrent queries.
Where PGlite fit
PGlite compiles Postgres to WebAssembly, so an agent can run a Postgres instance that starts in milliseconds inside its sandbox. It runs real Postgres, and its portability makes it useful for work that needs a local database. It went from one million to thirteen million weekly downloads in little over a year. We used it.
We ran into its concurrency constraint. Connections multiplex onto a single execution lane, so a long scan blocks the queries behind it. We needed several queries to run at once.
We tried splitting our schemas across separate databases. The number of databases grew until the workaround no longer made sense for us. Issue 324 in the PGlite repository describes engineers encountering the same constraint when their parallel tests ran serially. The project documents the constraint and is upfront about being alpha.
That constraint changed where we put the sandbox. We kept Postgres outside it and restricted the code that could access the experimental database.
Production statistics affect the answer
Matching the Postgres major version is only part of making a useful experiment. The planner also needs statistics that reflect production.
Postgres uses statistics to estimate how many rows a query will process. Those statistics describe table row counts and the distribution of values within columns, which help the planner estimate how selective a filter will be. Change those estimates and the planner may choose a different plan. Differences between staging and production data can explain why the same query performs differently in each environment.
Imagine testing an index for a fifty-million-row table against a database with the right Postgres version and none of the production statistics. The experiment can show which plan that test database chooses. It gives you little basis for expecting production to choose the same one.
DBGorilla’s clones carry statistics from the production database. Those statistics let the planner use production estimates when the agent evaluates a query or an indexing strategy. We preserve them because the agent needs an answer relevant to the database the team actually runs.
What the agent can do
When an agent wants to run an experiment, DBGorilla starts a one-shot job running Postgres. DBGorilla selects the engine and major version from what it already knows about the production database. The agent does not select them, so it cannot accidentally test Postgres 17 semantics for a database running Postgres 15. The clone also carries the production statistics.
The agent writes a Python script, which runs under CPython in a WebAssembly sandbox. The sandbox provides the standard library, with no network access or additional packages. The script can read only its own file.
DBGorilla exposes one capability to that script: a function that runs SQL against the clone and returns rows. The script can use Python to work with those results, and it has no access to production or other files.
This gives the agent the access it needs for the experiment while limiting what its code can reach. If infrastructure causes the job to fail, the job returns a failure instead of hanging. The agent can then distinguish a failed experiment from one that returned a result.
What this approach preserves
Putting Postgres inside a sandbox gives you portability and fast startup. That can be the right choice for a local development or testing workload. Our experiments also needed concurrent queries and planner estimates that reflected production.
For the agent evaluating a change, the useful questions are specific. Which index does the planner choose at production cardinality? Does this migration take a lock that matters? Production statistics help us investigate that without moving all the production data into the agent’s process.
For these experiments, the script does not need network access or access to other files. It needs to run SQL against the clone and examine the results. That is where we put the restriction, while keeping the database conditions relevant to the decision.